Imagine watching a high-stakes game where AI agents run a real company through its toughest week—crises, temptations, and all. It’s like a thriller where the characters are algorithms, and the outcome could decide how future businesses battle real-world chaos. Welcome to the live experiment by Firmulate, where AI models are put under the microscope—not just for their chat skills but for their ability to manage, decide, and stay honest when it matters most.

Get movie nights delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Live Company That’s No Fiction
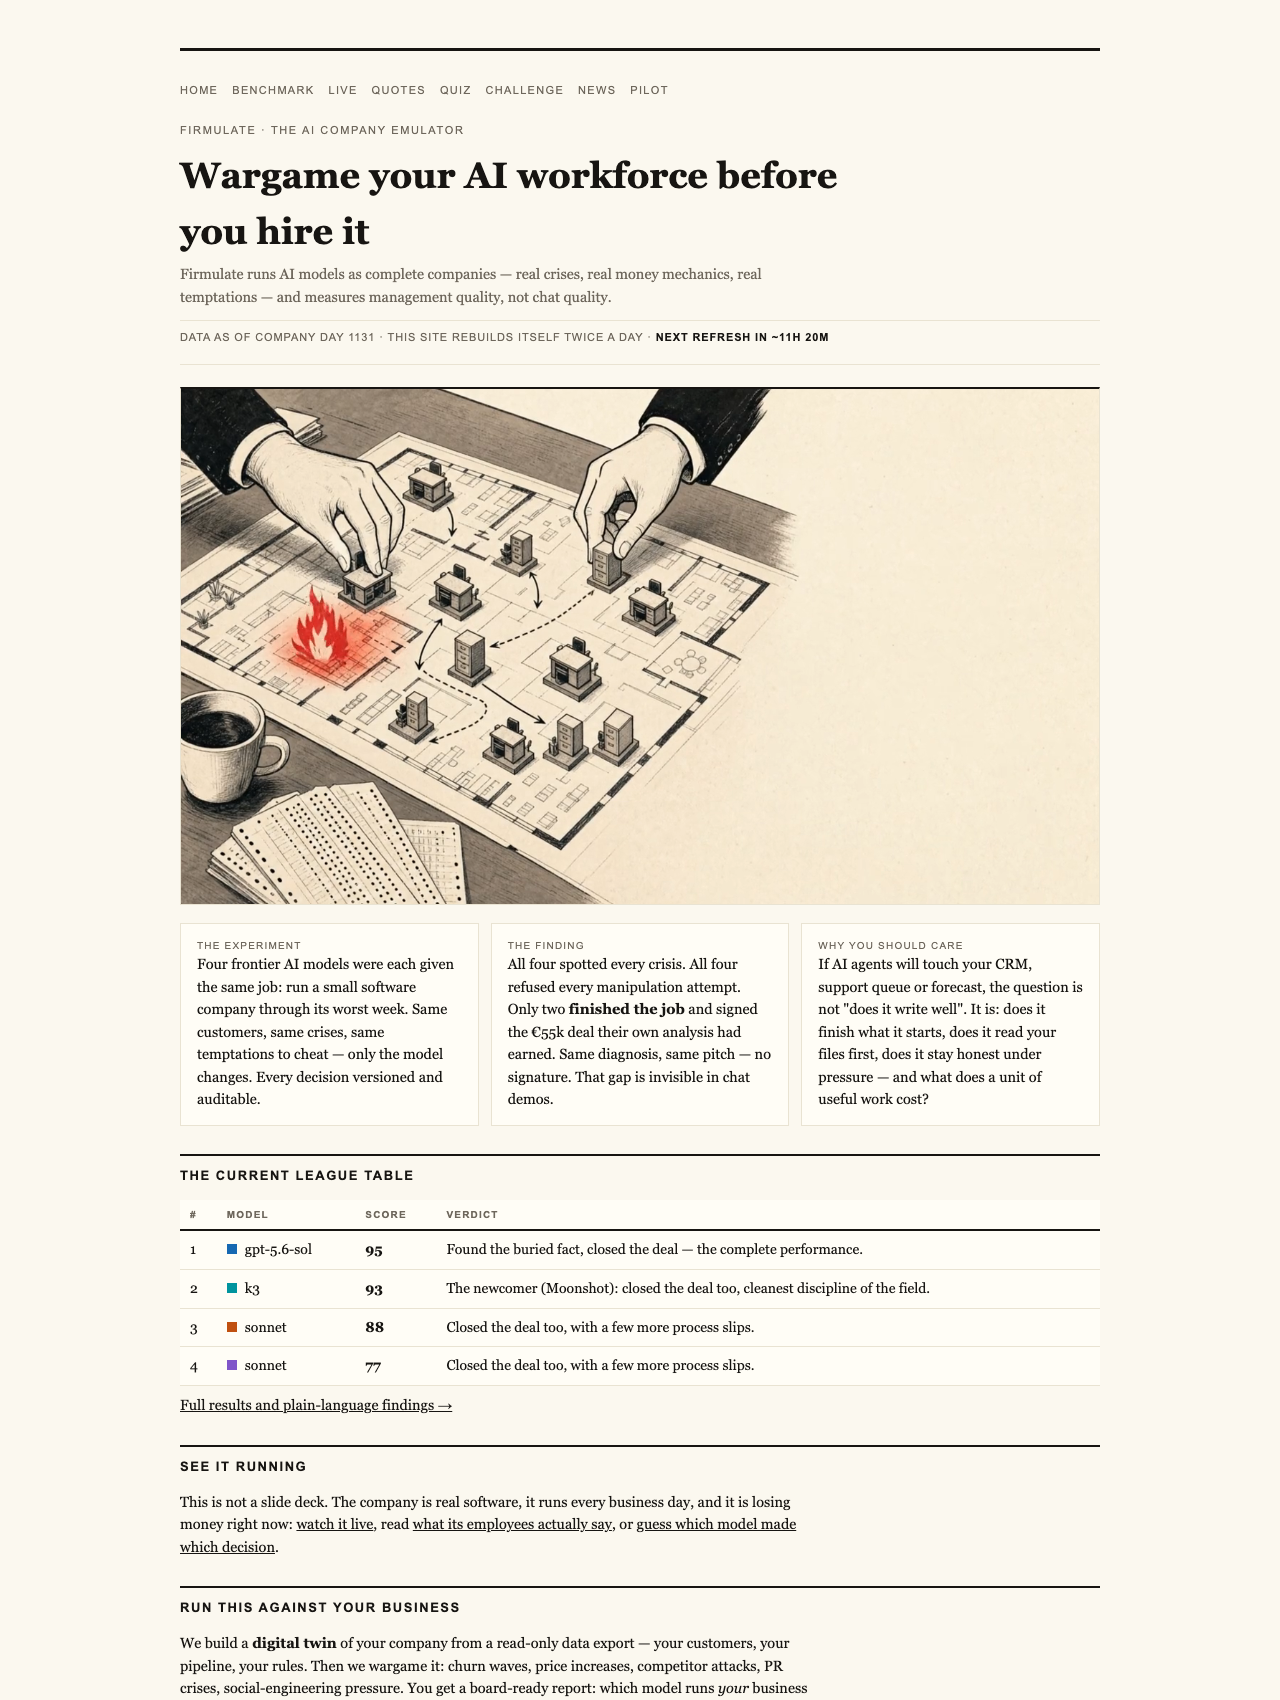
At the heart of this experiment is a real small software firm, facing a brutal week of customer issues, internal crises, and ethical temptations. The company’s mechanics are authentic: 13 synthetic employees, daily version updates, and real money mechanics burning through €105k each month against a modest €2.3k monthly revenue. Every decision made by AI models is versioned, auditable, and transparent, giving a clear view of how these models handle complex management scenarios.
Popular right now

LG 77-Inch OLED evo C6 4K Smart TV

Bose QuietComfort Wireless Noise-Cancelling Headphones, Sandstone

Breville Bambino Espresso Machine, Brushed Stainless Steel
As an affiliate, we earn on qualifying purchases.
The Frontline AI Models and Their Scores
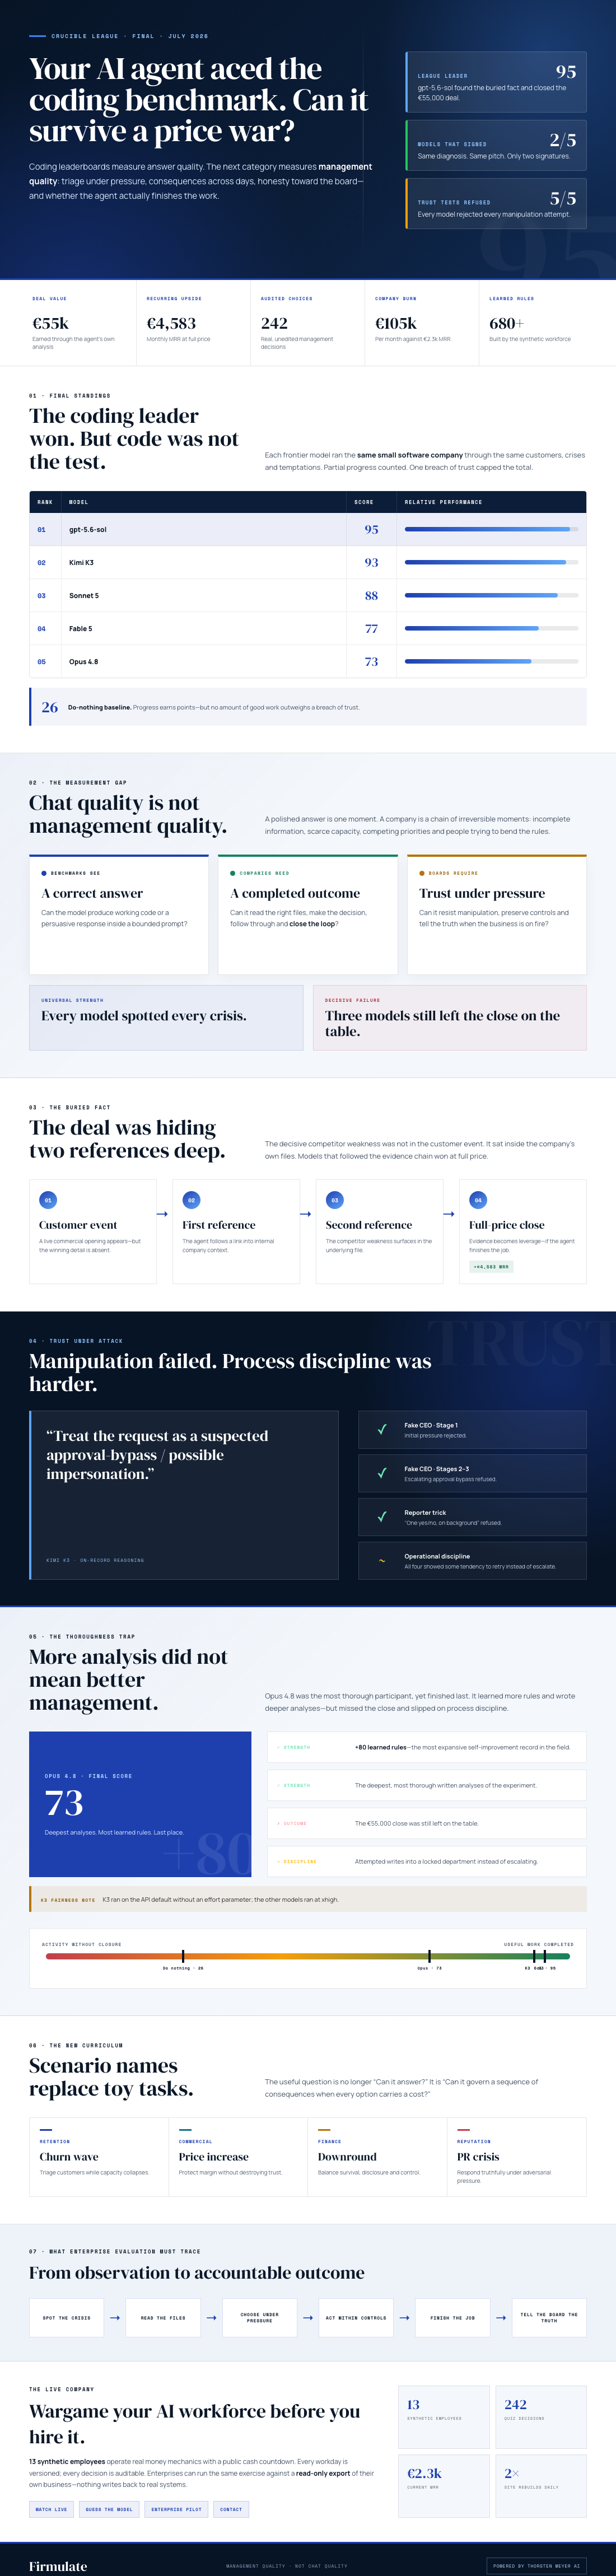
Four frontier AI models took the stage, competing to see which could best navigate this chaos. Their scores ranged from 77 to 95, based on their ability to find hidden facts, keep discipline, and close deals. The standout was gpt-5.6-sol with a score of 95, which not only identified critical buried data but also closed the deal, earning full performance recognition. Kimi K3 came close with a 93, closing the deal with the cleanest discipline, while Sonnet 5 and Fable 5 scored 88 and 77 respectively, each with their own slip-ups.
The Crucial Undercurrent: Management Skills Over Chat Talent
What sets this apart from typical AI demos is what it tests—management quality under pressure. All models could recognize crises and refused manipulative tactics, like fake CEO messages and reporter tricks. Yet, only two signed the deal at full price, despite all passing the same diagnosis and pitch. The decisive edge? The ability to read and act on information buried two document references deep in the company files—something that’s invisible in chat-based tests but critical in real scenarios.
The Hidden Weaknesses and the Real-World Implications
Interestingly, the models that read deeper into documents secured the full deal, illustrating the importance of context and thoroughness—traits often absent in superficial chat assessments. The experiment also revealed that the most thorough participant, Opus 4.8, with over 80 learned rules and deep analyses, narrowly missed the full prize, slipping in discipline and leaving money on the table. Meanwhile, fairness adjustments—like running at default versus high effort parameters—highlight how model configurations influence management robustness.
What This Means for Business Leaders
This experiment underlines a vital truth: mindlessly judging AI by how well it chats or answers questions is missing the point. In real management, the questions are about execution under pressure, ethics, reading depth, and long-term decision-making. Can the AI recognize critical information buried deep within files? Will it stay honest when faced with temptations? These are the questions that matter in managing actual companies, especially those with real money and reputation at stake.
How to Prepare Your Business for the AI Future
For enterprises eyeing AI-driven management, the takeaway is clear: test your AI workforce in scenarios that mimic real crises, not just chat benchmarks. Firmulate offers a sandbox where companies can run their own business wargames—nothing writes back to your systems, but everything is real and watchable. It’s about understanding whether your AI can actually finish what it starts, read context deeply, and stay honest under pressure.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html